AI assistants need more than website text to provide complete answers, but not every image, document, or transcript is suitable for retrieval. This blog explores how content review, approval, and update controls help organizations incorporate these sources while keeping AI responses accurate, relevant, and trustworthy.
Public sites now contain more than HTML. Provider directories include headshots. Program pages link to PDFs. Event pages embed or link to recorded sessions. An assistant that can only read the text on the page will miss information that a visitor can see, and an assistant that ingests every attached file without review will surface outdated or unintended content.
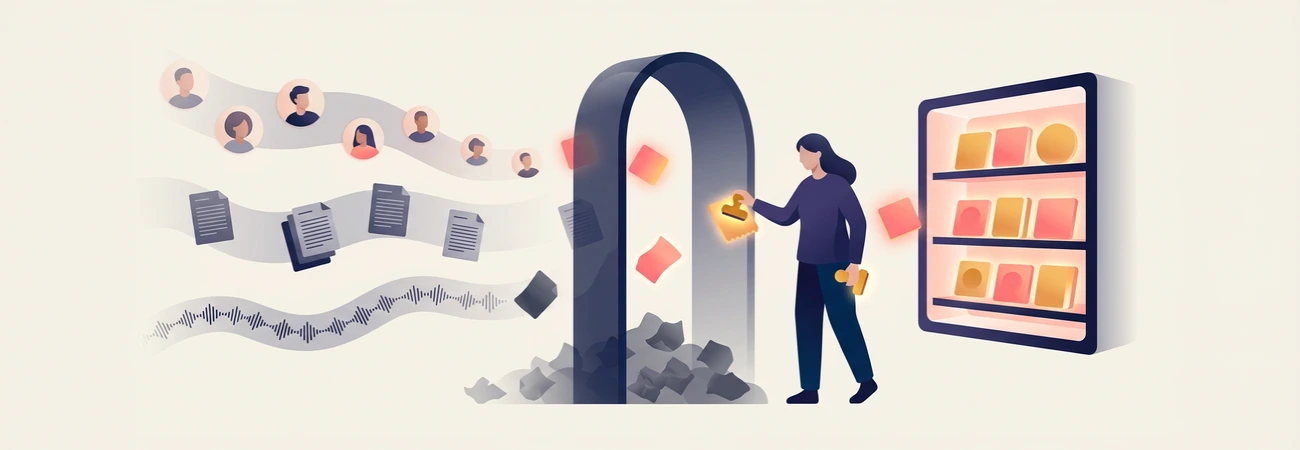
We treat images, documents, and transcripts as additional sources that follow the same rules as ordinary pages. They are inventoried, cleaned or excluded, and allowed into retrieval only after a person has confirmed they are current and appropriate to cite.
Images need text alternatives that match their purpose
A headshot on a staff directory is useful to a visitor and rarely useful to an assistant answering a question about office hours. A diagram that shows the steps in an application process is useful to both if the steps are also written out as text. We do not rely on a model to generate alt text for every image and then add the image to the retrieval index.
For images that carry information not already present in the surrounding text, a reviewer writes or approves a short description that states the facts the image conveys. That description is stored with the image and is what the retrieval system indexes. The image file itself is not sent to the model at query time unless the use case specifically requires visual question answering, which is uncommon for the public sites we work on.
Decorative images and images whose only purpose is branding are marked so they are skipped. This prevents the assistant from citing a stock photo as evidence for a program detail.
Documents are converted or excluded
PDFs and office documents are common on government and healthcare sites. Many of them are exports that contain the same information as an HTML page, or they are scanned images with no text layer. We run a conversion step that extracts text where a text layer exists and flags documents that are image-only.
Documents that duplicate an HTML page are excluded from retrieval so the assistant does not have two versions to reconcile. Documents that contain unique information are either converted into HTML sections on an existing page or are kept as citations only after a reviewer confirms the content is current. Scanned documents without a text layer stay out of the index until they are replaced or transcribed. An assistant that cites a scanned flyer from two years ago creates more problems than it solves.
The conversion step records the source file name, the date of the file, and the reviewer who approved the extracted text. When the source file is later updated, the extracted text is marked stale until the new version is reviewed.
Transcripts require the same factual check as any other page
Recorded meetings, training sessions, and public hearings produce transcripts that look like rich source material. They also contain asides, outdated statements, and remarks that were corrected later in the same session. We do not add a raw transcript to the retrieval corpus.
A reviewer, or a summarization step followed by a reviewer, produces a cleaned version that removes off-topic remarks and flags any statement that conflicts with current policy. Only the cleaned version is eligible for retrieval. The original transcript remains available as a download for people who need the full record, but it is not what the assistant reads.
This extra step is what keeps an assistant from answering a question with a remark a speaker later withdrew. The time it adds is usually less than the time required to correct the resulting public answer.
The review gate is the same one used for pages
Images, documents, and transcripts do not get a separate, lighter approval path. The same content owner who would approve a new HTML section approves the text that will be indexed from these sources. The approval includes a check that the material does not contain personal information that should not be public and that it does not contradict the current HTML pages on the same topic.
When the material fails that check, it is excluded and the reason is recorded. The exclusion appears in the same inventory the team uses for ordinary pages, so a later audit can see the full set of sources the assistant is allowed to use.
Operational limits that keep the system maintainable
We limit the types of files the pipeline will accept. A site that begins ingesting every uploaded spreadsheet and every internal presentation quickly exceeds the team's ability to review them. The allowed types are declared in advance: current program PDFs, approved transcripts of public sessions, and images whose approved descriptions have been written. Everything else is left out until someone makes a case for adding it and accepts the review work.
Refresh schedules match the update frequency of the source. A quarterly program guide is rechecked quarterly. An event transcript is reviewed once and then left unchanged unless the organization issues a correction. The index drops any item whose review date has passed the allowed window.
Multimodal retrieval adds sources the assistant can cite. It also adds sources the assistant can misuse if they are stale, contradictory, or unreviewed. Treating those sources with the same inventory, exclusion, and approval steps used for ordinary pages keeps the assistant's answers inside the set of material the organization has already decided to stand behind.